
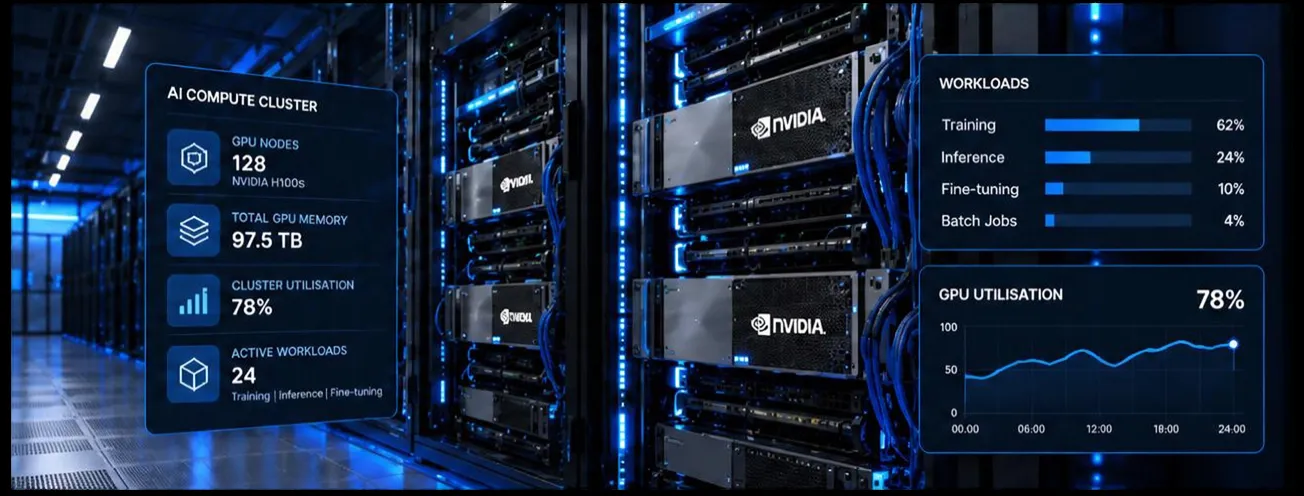
Build. Orchestrate. Meter. Monetise.
From physical GPU infrastructure to a managed compute service. We combine AI servers, orchestration, metering, and token or credit-based access into one model, so compute is allocated fairly, tracked precisely, and paid for by use.
Private or shared clusters Metered by usage Credit or token access
- GPU-01 · Fine-tune · Finance LLM 92%
- GPU-02 · Inference · Support bot 71%
- GPU-03 · Training · Vision model 88%
- GPU-04 · Idle · available 6%
GPU hours today
61.4 h
Team credits left
8,420 / 12,000
Capabilities
Everything between the GPU and the invoice.
GPU infrastructure
Compute orchestration
Usage metering
Tokenized access
Tokenized AI compute
How we package GPU infrastructure into a metered service.
- 01
GPU clusters
AI servers, storage, and network foundation.
- 02
Orchestration
Container workloads, scheduling, and resource allocation.
- 03
Usage metering
GPU hours, jobs, memory, and utilisation.
- 04
Token / credit engine
Usage converted into credits or token-based access rules.
- 05
Consumption & settlement
Users run workloads, consume balances, and receive reports.
GPU cluster → Workload orchestration → Usage metering → Token / credit access → Users & applications
What we deliver
Compute capacity, delivered your way.
GPU-as-a-Service
Private or shared clusters
Metered commercial model
Operational visibility
Workloads
Built for the full AI lifecycle.
Training
Inference
Fine-tuning
Monetised idle capacity
Serve private models through one governed API.
Put AI Gateway in front of models running on your own GPUs, and applications reach them through the same OpenAI-compatible API and policies as any cloud provider.
Get started
Turn GPU infrastructure into a managed, metered service.
Tell us about your workloads, users, and how you want compute billed. We'll design the cluster, orchestration, and metering model around them.